

Every marketing ops team I have worked with is busy. Tickets get closed. Dashboards get built. Automations ship. And then sales ignores most of it, and nobody can explain why.
The reason is not that the work is bad. It is that marketing ops is usually run as a service desk. A request comes in, the team builds it, the team moves on. Delivery is the scoreboard. Adoption is never measured at all.
That is the trap, and it is one of the biggest reasons marketing ops ships more every quarter and moves less. The fix is not more tools or more headcount. It is running ops like a product team instead of a ticket queue.
TL;DR
- The Trap: Marketing ops runs as a ticket queue, so it optimizes for delivery instead of adoption.
- The Reframe: Treat ops as a product with real users (the revenue team), a roadmap, and instrumentation.
- The Loop: Discover, Instrument, Ship, Adopt. Adoption is the only output that counts.
- The Evidence: Teams ship constantly and still watch most of their content go unused by sales.
- The Start: Measure one thing this quarter: is the revenue team actually using what you built?
What Marketing Ops as a Product Actually Means
Running marketing ops as a product means treating the revenue team as your users and adoption as your only release. The unit of work is a user getting an outcome, so you name the user, decide up front how you will know the build worked, ship the smallest usable version, and chase adoption until the number moves. Delivery opens the job. Adoption closes it.
The Service Desk Trap
Service desks are built to answer, not to be adopted. The measure of a service desk is response time and ticket volume, and both of those go up when the underlying problem never gets fixed. A help desk that ships a report nobody reads still counts it as a win, because the ticket closed.
Marketing ops inherits the same instinct. Someone asks for a campaign dashboard, a lead routing rule, an attribution model. Ops builds exactly what was asked. The requester nods in the handoff meeting. Three weeks later the dashboard has two viewers, and the routing rule is being worked around in a spreadsheet nobody approved.
The service-desk model hides that failure, because it only measures the moment of delivery. It never measures the moment of use. That is the same blind spot that makes so many teams measure output instead of impact. Volume is easy to count and easy to report, so volume becomes the story.
The problem is not that marketing ops ships too little. It is that it almost never finds out whether anyone used what it shipped.
The Incentive That Keeps You a Service Desk
It is worth being honest about why the service-desk model survives. It is not laziness. It is incentives.
Service desks get rewarded for responsiveness. The request comes in, the clock starts, and the hero is whoever closes the ticket fastest. Nobody gets praised for the report that got adopted six weeks later, because by then everyone has forgotten which request it came from. Speed is visible. Adoption is invisible.
There is also a comfort in the queue. A ticket is finite. A user’s outcome is messy, because it depends on someone else changing their behavior, and you cannot close a ticket for that. It is far easier to declare victory at delivery and move to the next request.
That is exactly why measurement has to come before motivation. You cannot ask an ops team to optimize for adoption while the only number anyone tracks is throughput. Change the scoreboard first, and the behavior follows.
Your Users Are the Revenue Team, Not the Requester
The first shift is refusing the ticket as the unit of work. The unit of work is a user getting an outcome.
Who are the users of marketing ops? Not the person who filed the request. The users are the people downstream who have to act on the output: the SDR working the list, the AE opening the call, the demand-gen lead deciding where to spend, the content lead deciding what to build next. The handoff between marketing and sales is where ops work either lands or dies.
Once you name the real users, a different question appears. Not “did we deliver it” but “is it changing what a human does on Monday morning.” A lead score nobody trusts is not a product. A routing rule sales ignores is not a product. A content calendar nobody follows is not a product.
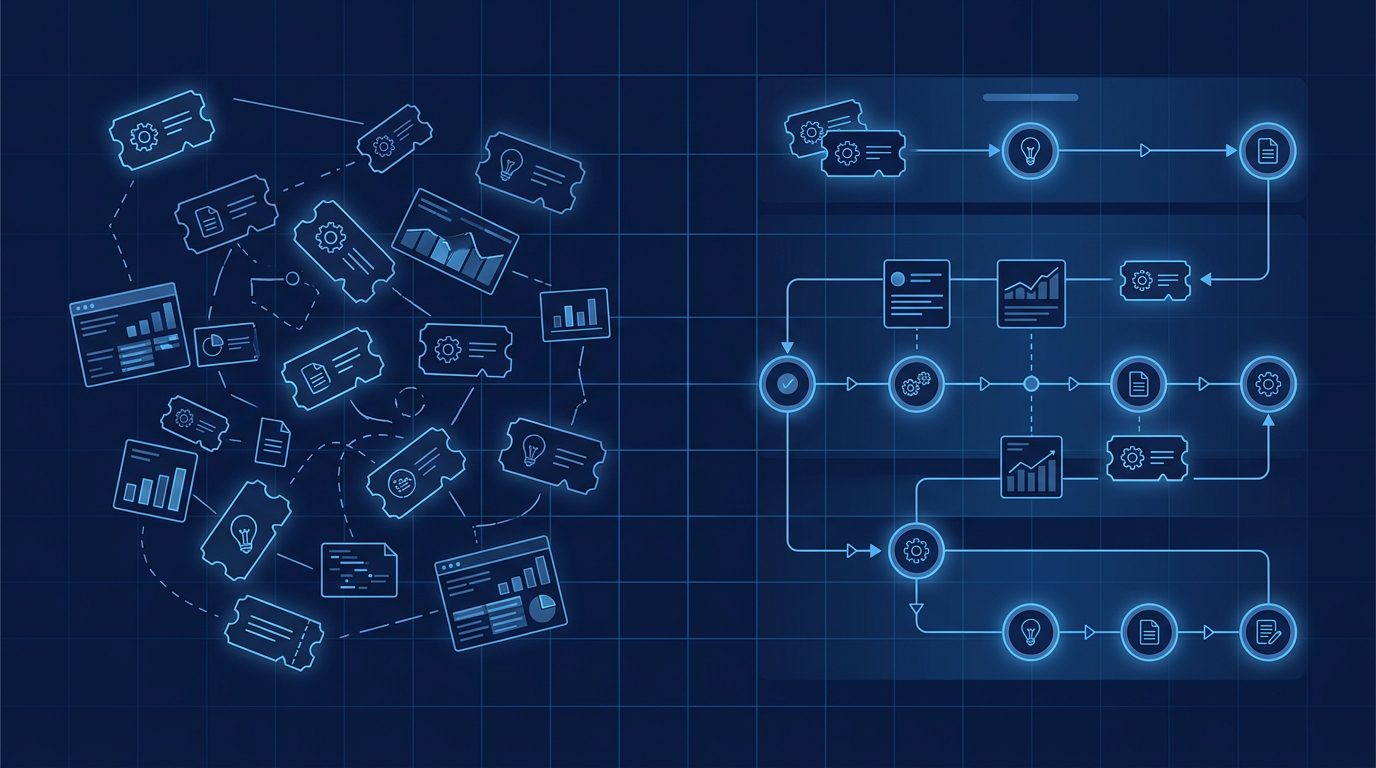
| Dimension | Service Desk | Product Team |
|---|---|---|
| Unit of work | The ticket | The user’s outcome |
| Success metric | Delivered on time | Adopted and used |
| Roadmap | Inbound requests | Prioritized problems |
| Feedback signal | Requester satisfaction | Usage data and objections |
| Failure mode | Busy and unused | Sparse and adopted |
The Ops Product Loop
Running ops as a product does not require a product manager. It requires four habits, in order, every time. The discipline is the sequence: you cannot instrument what you have not defined, and you cannot adopt what you have not instrumented.
Before you build, write down who the user is and what they will do differently. If you cannot name the behavior change, you do not have a spec. You have a wish.
Decide how you will know it worked before you ship. Viewers, follows, replies, time-to-action, spreadsheet workarounds. If a build has no adoption signal, it has no feedback loop, and it will drift.
Ship the smallest version a real user can use this week. A routing rule for one segment beats an enterprise workflow nobody has configured.
Then watch. Chase the first ten users personally. Fix what confuses them. Kill what nobody touches. Adoption, not delivery, is the release.

Marketing ops does not have a delivery problem. It has an adoption problem. I stopped measuring what my team shipped and started measuring what sales actually opened. The stack did not change. The results did.

What I Learned Running Ops Both Ways
I have run marketing ops as a help desk and as a product, and the difference is not subtle.
As a help desk, we shipped exactly what was requested, on time, and reported healthy ticket throughput. We also watched the same problems come back quarter after quarter, because nothing we built changed the way anyone actually worked. The team was exhausted and the pipeline did not move.
As a product, the first thing we shipped was small: one routing rule for one segment of leads, plus a simple way to see whether reps were working them. They were not. That single fact, visible for the first time, was worth more than the previous year of dashboards. We fixed the rule, adoption went up, and speed-to-first-touch became a number the whole team watched.
The uncomfortable part is that the help-desk version of the team was working just as hard. The work was real. It was simply pointed at delivery instead of adoption, and delivery does not compound. Adoption does, because every person who actually uses the thing becomes a reason the next thing gets used.
Here is the lesson I would give any ops lead: your roadmap should look like the biggest un-adopted thing you have already built, not the next new thing on someone’s wish list.
How to Start This Quarter
Name three people downstream whose behavior depends on it. If you cannot name three, you cannot measure adoption, and you are not ready to optimize it.
A view count, a follow, a reply, a usage log. Anything that tells you the build is being used, not just delivered.
If you cannot get ten people to use it, you do not have a product yet. You have a prototype with a launch email.
Every quarter, kill an ops asset nobody uses. Adoption debt is real, and unlike technical debt it quietly eats the trust you need for the next launch.
Three Signals You Have Real Adoption
- People ask for the next version. Requests for changes are the strongest adoption signal there is, because they mean the first version is in the workflow.
- It survives a busy week. If usage holds on your team’s worst week, it has become a habit. If it only spikes after a launch email, it is still a campaign, not a product.
- Someone defends it. When a user argues to keep a tool during a budget review, you have adoption. When nobody notices it is gone, you never had it.
The Only Scoreboard That Matters
Delivery metrics feel good and mean little. Tickets closed, automations built, dashboards shipped: none of them tell you whether marketing ops is working. They tell you the team was busy, which was never in doubt.
Adoption is downstream of one question: is the revenue team doing something differently because of what we built? That is the same problem underneath attribution you cannot trust and reports built on AI adoption numbers that sound great and change nothing. According to the Content Marketing Institute, the use of AI in marketing is close to universal, and confidence in the output is not. The gap between those two numbers is an adoption problem wearing a technology costume.
Marketing ops should be measured the way a product is measured: by what its users keep using after the launch announcement is forgotten.
Marketing ops does not need to ship more. It needs to find out what its users actually use, then do more of that and less of everything else.
Marketing Ops Questions, Answered
What is the difference between marketing ops and RevOps? RevOps owns the revenue process end to end across marketing, sales, and customer success. Marketing ops usually owns the systems and data marketing runs on. The product-team model applies to both: if the output never changes how a human works, it is not finished.
How do I measure adoption of a marketing ops build? Pick one behavior downstream of the build and count it. Dashboard viewers, routing-rule overrides, follow-ups on a routed list, time-to-first-touch on new leads. If nobody’s behavior changes, the build failed no matter how clean the delivery was.
Should marketing ops have a roadmap? Yes, and it should open with the biggest thing you already built that nobody adopted. New requests come second, because an un-adopted build is a sunk cost you can still recover.
How many users do I need before a build counts as adopted? Ten is the honest bar. Below that, you are still testing whether the thing works, not running a product.